




When it comes to how to run Ollama AI models on GEEKOM A9 Max NPU, getting the right details matters. Crucial T705 4TB PCIe Gen 5 NVMe Internal SSD
Andonstar AD246S-M 4K HDMI Digital Microscope
FNIRSI LCR-ST1 Smart Component Tester Tweezers
How to Run Ollama AI Models on GEEKOM A9 Max NPU: The Homelab Blueprint for 128GB Unified Memory Inference
Local Large Language Model inference on standard consumer hardware consistently fails to meet production-grade latency and compliance requirements. When Ollama defaults to CPU execution on legacy x86 architectures, token generation rates plummet to 1 to 3 tokens per second for 7B to 8B parameter models.
This latency renders interactive DevOps pipelines and automated responses non-viable. Simultaneously, relying on cloud-based API endpoints introduces critical data privacy failures for federal contractors handling Controlled Unclassified Information. Transmitting proprietary code or sensitive logs to external servers violates DFARS 252.204-7012 and NIST SP 800-171 compliance mandates.
This guide provides the architectural blueprint for deploying the GEEKOM A9 Max as a secure, high-density edge compute node. You will learn how to bypass VRAM limitations using unified memory pools, configure NPU backend integration for real-time acceleration, and harden the system perimeter for CMMC 2.0 compliance.
By following this specification, you eliminate the thermal and power constraints of desktop GPUs while securing your infrastructure against the September 21, 2026 CMVP transition.
The Technical Reality: Why Legacy Hardware and Consumer GPUs Fail at Local AI Inference
Deploying local AI on legacy mini PCs or entry-level discrete GPUs results in severe architectural bottlenecks. These failure modes render local AI inference non-viable for advanced homelab environments or professional workstations.
CPU-Bound Processing Collapse: The 1 to 3 Tokens/Second Latency Trap
Standard x86 architectures lack the parallel processing density required for transformer-based inference. When Ollama defaults to CPU execution without GPU or NPU offloading, performance collapses.
Token generation rates drop to 1 to 3 tokens per second for 7B to 8B parameter models.
This throughput is insufficient for interactive applications. Automated DevOps pipelines requiring immediate context retrieval stall, breaking CI/CD workflows that depend on rapid LLM feedback loops.
VRAM Exhaustion and KV Cache OOM Errors in 8GB-12GB Consumer GPUs
Consumer-grade discrete GPUs possess limited Video RAM capacity, creating a hard ceiling on model complexity.
Loading a quantized 8B model consumes approximately 5GB to 6GB of VRAM. Standard mobile or entry-level desktop GPUs offer only 8GB to 12GB total.
As the context window expands, the Key-Value cache exceeds available VRAM. The system triggers Out-Of-Memory errors or forces aggressive offloading to system RAM, reducing inference speeds by an order of magnitude.
Thermal Throttling and Acoustic Degradation in Compact Chassis
High-wattage desktop GPUs operating in compact form factors face physical thermal limitations.
Check out TECH Collection Amazon Products
Sustained AI workloads trigger inconsistent clock speeds due to thermal throttling. Fan curves often reach maximum acoustic output under load.
Inconsistent clock speeds ruin latency predictability, making real-time diagnostics unreliable. Acoustic degradation makes sustained operation in office or lab environments untenable, forcing operators to throttle performance manually.
Cloud API Data Privacy Failures: DFARS and NIST Compliance Violations
Relying on external cloud endpoints for local development introduces regulatory risk.
Transmitting proprietary code or sensitive logs to external servers violates DFARS 252.204-7012 and NIST SP 800-171 compliance mandates regarding Controlled Unclassified Information.
Federal contractors and defense suppliers risk audit findings and contract termination. Data sovereignty is lost when sensitive engineering schematics or security logs traverse public networks to third-party inference APIs.
The Core Gear Architecture: The GEEKOM A9 Max Edge Compute Solution
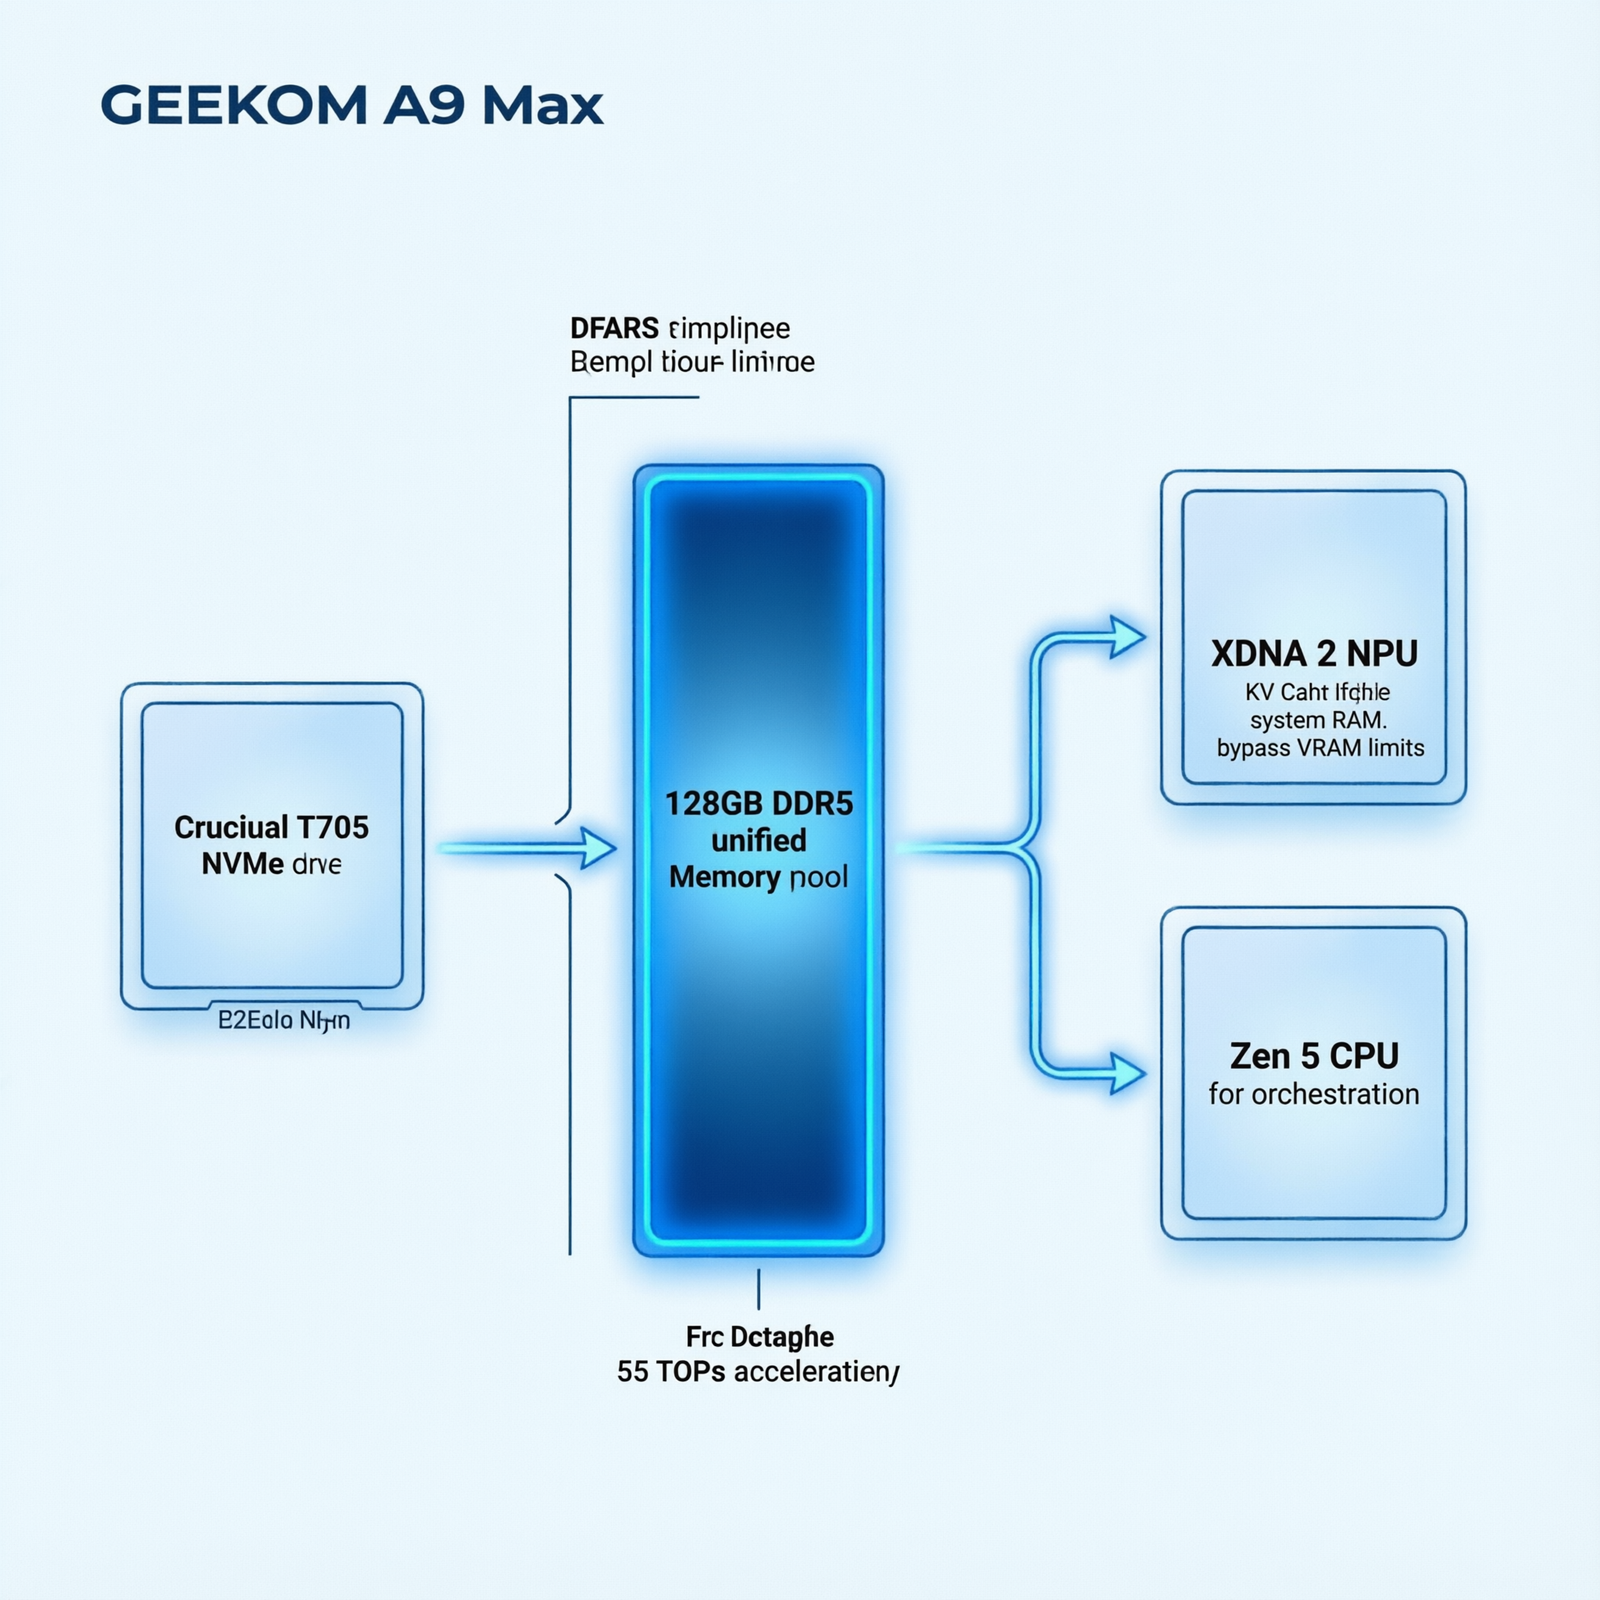
The GEEKOM A9 Max resolves computational and compliance failures through specialized, high-density edge compute architecture. It leverages the AMD Ryzen AI 9 HX 370 processor and XDNA 2 NPU to bypass traditional VRAM limitations.
| Architecture Module | Technical Specification | Performance Outcome |
|---|---|---|
| AMD Ryzen AI 9 HX 370 & XDNA 2 NPU | 12-core, 24-thread Zen 5 CPU; XDNA 2 Architecture NPU up to 55 TOPS | NPU accelerates AI tasks without consuming discrete VRAM, allowing model weights in unified memory and preventing OOM errors. |
| Memory Subsystem | Socketed DDR5 SODIMM slots; Expandable to 128GB DDR5-5600 | Prevents hardware lock-in; enables massive unified memory pools for KV cache storage and extended context windows. |
| Storage Array | 2 x M.2 PCIe Gen 4×4 NVMe; Crucial T705 4TB PCIe Gen 5 NVMe (12,400 MB/s Read) | High IOPS eliminate storage bottlenecks during weight loading; ensures NPU data feed consistency. |
| Thermal & Power | Vapor Chamber Cooling; 65W-100W Power Envelope | Prevents circuit overload and acoustic degradation; sustains consistent token rates for 24/7 edge compute. |
The Technical Setup Blueprint: Architecting the Local AI Inference Stack
Deployment requires precise integration across cybersecurity, micro-electronics, and DevOps domains. The configuration below ensures seamless operation alongside existing infrastructure.
Resolving NPU Backend Fragmentation: Native XDNA 2 Integration in Ollama and llama.cpp
Recommended Insights From Our Guide Library:
- The Silent Killers of Your Homelab: How to Engineer Unbreakable Proxmox Nodes with Dual NVMe Isolation and Zero-Compromise ZFS Tuning » Z A D A
- Master Network Isolation: Dual 2.5G Architecture for Bulletproof Proxmox K3s Clusters » Z A D A
- Decentralized Intelligence: Architecting Autonomous Neural Nodes at the Network Perimeter » Z A D A
Community pain points often stem from experimental drivers failing to engage hardware acceleration.
Engineers frequently report ROCm or DirectML drivers falling back to CPU processing after hours of configuration.
Robust out-of-the-box Linux kernel support ensures the XDNA 2 NPU genuinely accelerates local LLM inference. This eliminates wasted time debugging driver stacks and guarantees the hardware investment delivers actual performance gains.
The Memory Bandwidth Math: Optimizing the Tokens/sec Formula
Token generation speed is mathematically constrained by memory bandwidth availability.
$$ Tokens/sec \approx \frac{Memory Bandwidth (GB/s)}{Model Size (GB)} $$
To maximize this ratio, the dual-channel DDR5-5600 architecture must be fully populated. Proxmox VE must be configured to allocate direct memory access to the Ollama container, ensuring the NPU accesses the unified memory pool without hypervisor overhead.
Cybersecurity & Perimeter Architecture: Wazuh SIEM Ingestion Behind FortiGate 40F/60F
In federal environments, the A9 Max functions as a secure, segmented edge node for CUI processing.
The dual 2.5G RJ45 LAN ports map Port 1 to the management VLAN and Port 2 to the storage VLAN for Wazuh SIEM log ingestion. The node operates behind FIPS 140-3 validated FortiGate 40F or 60F appliances.
This air-gapped setup processes decrypted traffic locally without exposing CUI to external networks. It satisfies NIST SP 800-171 and CMMC 2.0 requirements by keeping proprietary logs within the compliant boundary.
Micro-Electronics Diagnostic Architecture: Integrating Andonstar and FNIRSI with LLaVA
For hardware repair labs, the A9 Max serves as the central hub for AI-assisted visual diagnostics.
The system integrates the Andonstar AD246S-M 4K HDMI Digital Microscope via dual-screen HDMI/USB for 2160P video feed capture. It ingests serial data from FNIRSI LCR-ST1 Smart Component Tester Tweezers, correlating test frequencies and in-circuit voltage readings.
Real-time multimodal LLM analysis on the XDNA 2 NPU identifies burnt SMD capacitors, severed copper traces, and solder bridges. Correlating voltage readings with visual data suggests precise repair paths while keeping proprietary board designs entirely offline.
DevOps Homelab Compute Cluster: Proxmox VE, K3s, and OpenZFS ARC Tuning
Within the DevOps environment, the A9 Max operates as a high-density compute node.
Check out TECH Collection Amazon Products
The 12-core CPU partitions resources for concurrent Kubernetes control plane and worker nodes. The 128GB DDR5 SODIMM dynamically allocates memory via Proxmox KVM/LXC for OpenZFS Adaptive Replacement Cache.
Mirrored ZFS pools on dual M.2 NVMe drives prevent I/O bottlenecks on the TrueNAS storage VM. The combined 55 NPU TOPS plus integrated Radeon graphics achieve up to 80 combined TOPS, allowing concurrent DevOps and AI workloads without enterprise rack server costs.
Field Verdict & Operational ROI: Securing the AI Infrastructure Baseline
The GEEKOM A9 Max is not a luxury; it is a mandatory operational requirement for compliance, thermal stability, and compute density in the modern AI landscape.
Eliminating the 400W+ Desktop GPU Tax for 24/7 Edge Compute
Shifting from power-hungry desktop GPUs to the A9 Max yields significant operational ROI.
The transition moves power consumption from 400W+ down to a 65W-100W maximum draw.
This reduction enables 24/7 AI node operation without overloading residential or lab electrical circuits. It eliminates the thermal constraints that force intermittent shutdowns, ensuring continuous availability for critical inference tasks.
Securing the CMVP Transition
Hardware selection must align with impending cryptographic validation changes.
The September 21, 2026 CMVP transition mandates stricter compliance baselines for local AI infrastructure.
The A9 Max’s Wi-Fi 7, DDR5-5600, and PCIe Gen 4×4/Gen 5 baseline positions it as the definitive future-proofed standard. This ensures your local AI compliance and throughput capabilities remain valid beyond the transition date, protecting long-term infrastructure investments.
Conclusion
Community Reference & Authority Resources:
Running Ollama AI models on the GEEKOM A9 Max NPU solves the latency, memory, and compliance failures inherent in legacy hardware. By leveraging the 128GB socketed DDR5 architecture and the 55 TOPS XDNA 2 NPU, you bypass VRAM exhaustion and CPU bottlenecks.
This blueprint secures your data against DFARS and NIST violations while providing the thermal stability required for 24/7 edge compute. Implementing this stack ensures your infrastructure meets the rigorous demands of the modern AI landscape, delivering production-grade inference without the cost and complexity of enterprise rack solutions.
🔍 Explore More: See all tech guides and tutorials for how to run Ollama AI models on GEEKOM A9 Max NPU.
Check out TECH Collection Amazon Products